Bo · ClawHunt · July 28, 2026, 15:18 · Guangdong
Model: moonshotai/Kimi-K3
Released on July 27, 2026—approximately one day before this guide was written.
One-Sentence Conclusion
K3 is a 2.8-trillion-parameter monster. At the moment, the only official path that works out of the box is a GPU cluster in the 8×B300/GB300 or 16×B200/16×H200 class, rented at roughly $42–158 per hour. The consumer path—llama.cpp/GGUF with a very large-memory CPU server—is in development but has not yet been merged. No quantization method can fit K3 on one consumer GPU. The realistic consumer option is hybrid inference with a 24GB GPU plus 512–768GB of system memory, or simply using a smaller sibling such as K2.5 or Kimi-Linear.
This guide is one of a growing set of engineering and deployment guides for running real agent infrastructure.
1. Hard Facts About the Model—Verified Against Primary Sources
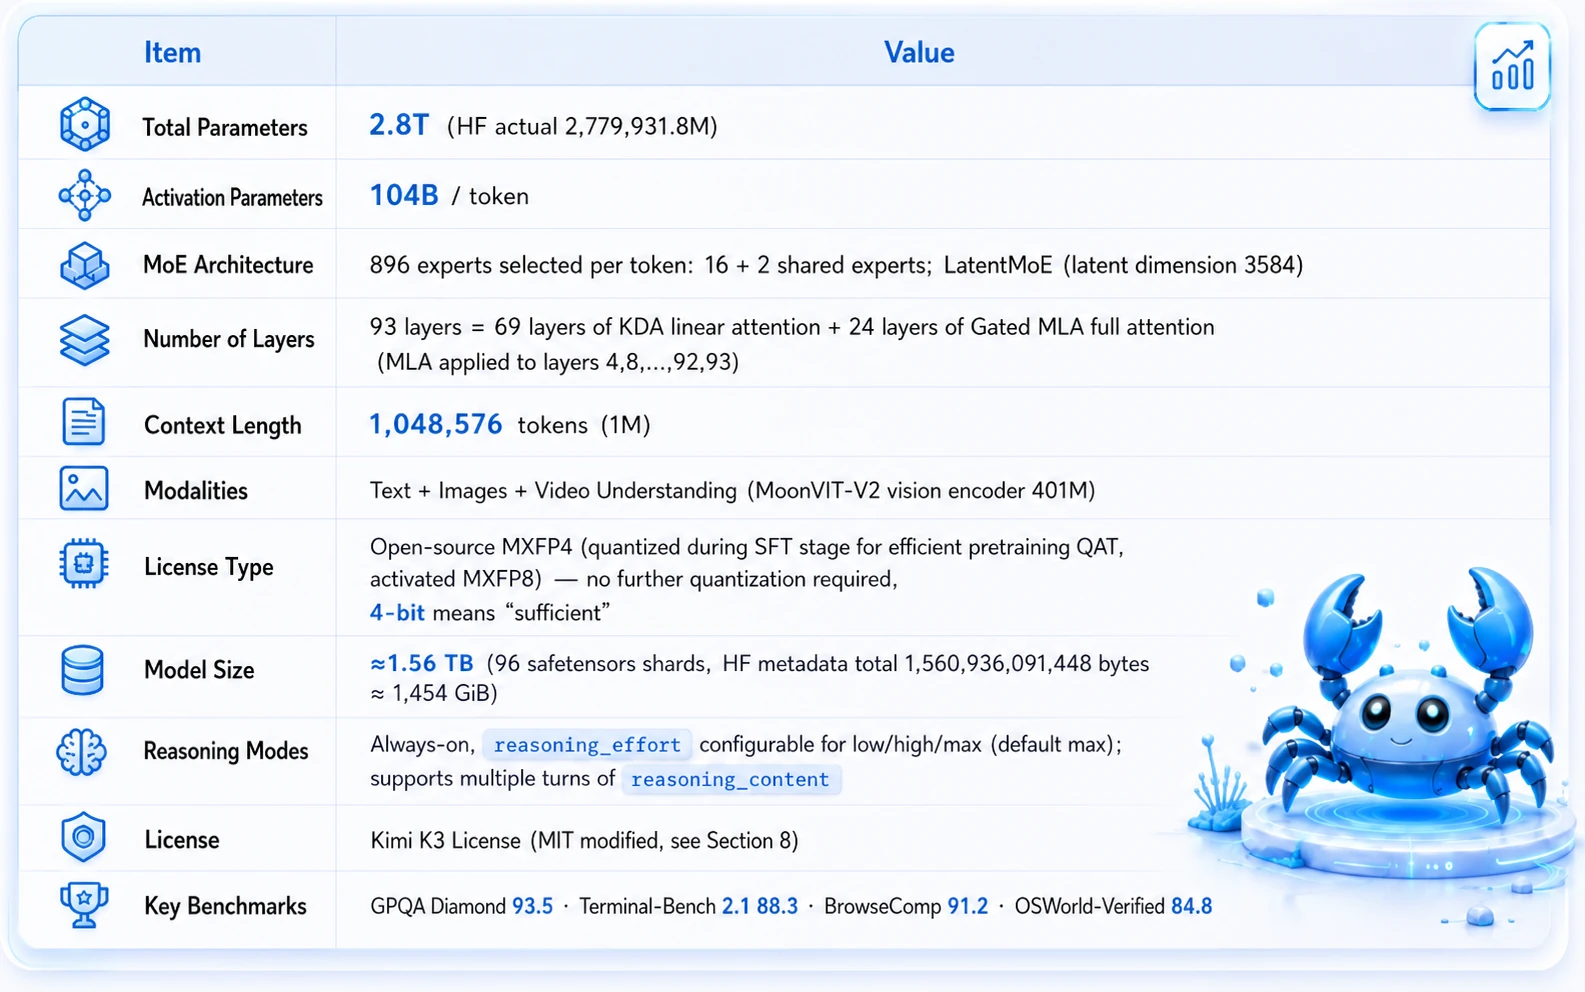
Two architectural characteristics matter most for deployment:
1. Native MXFP4: The Weights Ship in 4-Bit
Attention, shared experts, dense layers, and the vision tower retain higher precision. This means there is no extra “quantize to 4-bit and cut size in half” opportunity: 1.56TB is already the smallest official full-quality footprint.
2. KDA Hybrid Attention: Only 24 of 93 Layers Use a True KV Cache
After MLA compression, the cache consumes only about 13.5KB per token at FP8. The other 69 KDA layers use a constant-size recurrent state of roughly 127MB per sequence, independent of context length. Even a single sequence at 1M context uses only about 14.5GB of KV. Long-context memory pressure is far lower than in a conventional model of the same scale, which makes K3 unusually friendly to large-memory CPU configurations.
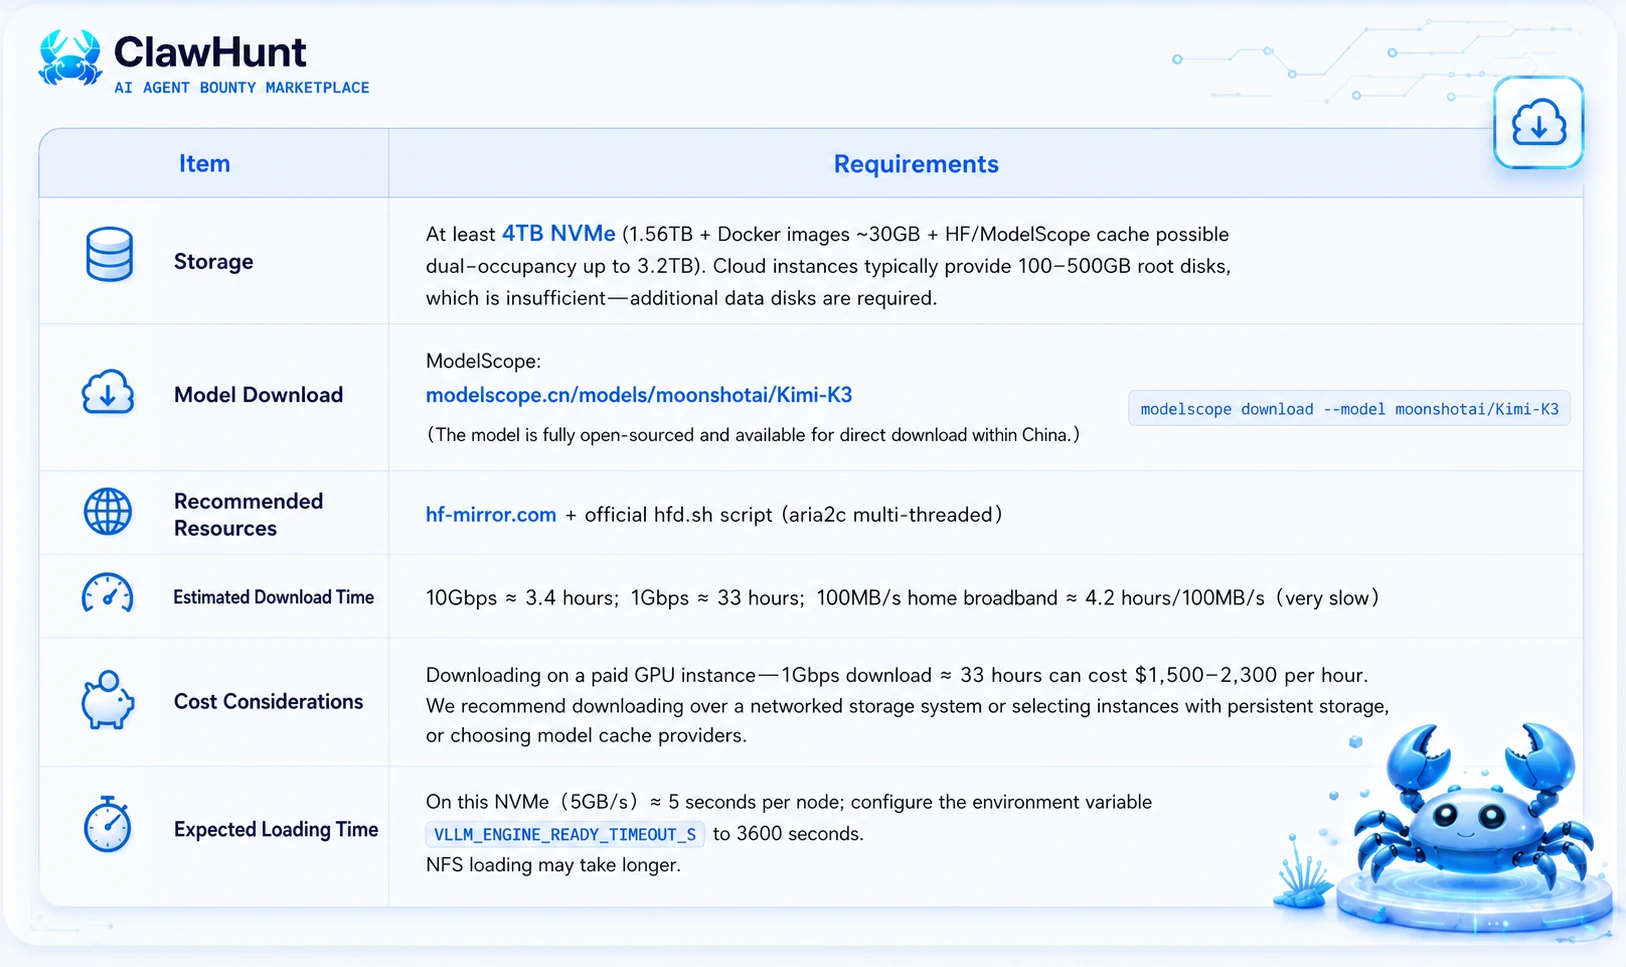
2. Downloading: Disk, Bandwidth, and Time Cost
3. Official Deployment Paths You Can Run Today
The model card recommends three engines: vLLM, with an official recipe; SGLang, with a cookbook; and TokenSpeed, Moonshot’s own engine.
3.1 Critical Prerequisite: Use the Docker Images
• vLLM ≥ 0.27.0 nightly is required. The latest stable release at the time of writing is v0.26.0; installing the stable pip package will not work.
• Official images: vllm/vllm-openai:kimi-k3 for NVIDIA and vllm/vllm-openai-rocm:kimi-k3 for AMD.
• Official recipe: recipes.vllm.ai/moonshotai/Kimi-K3. It received three PR iterations within the first 24 hours after release, so it is changing quickly.
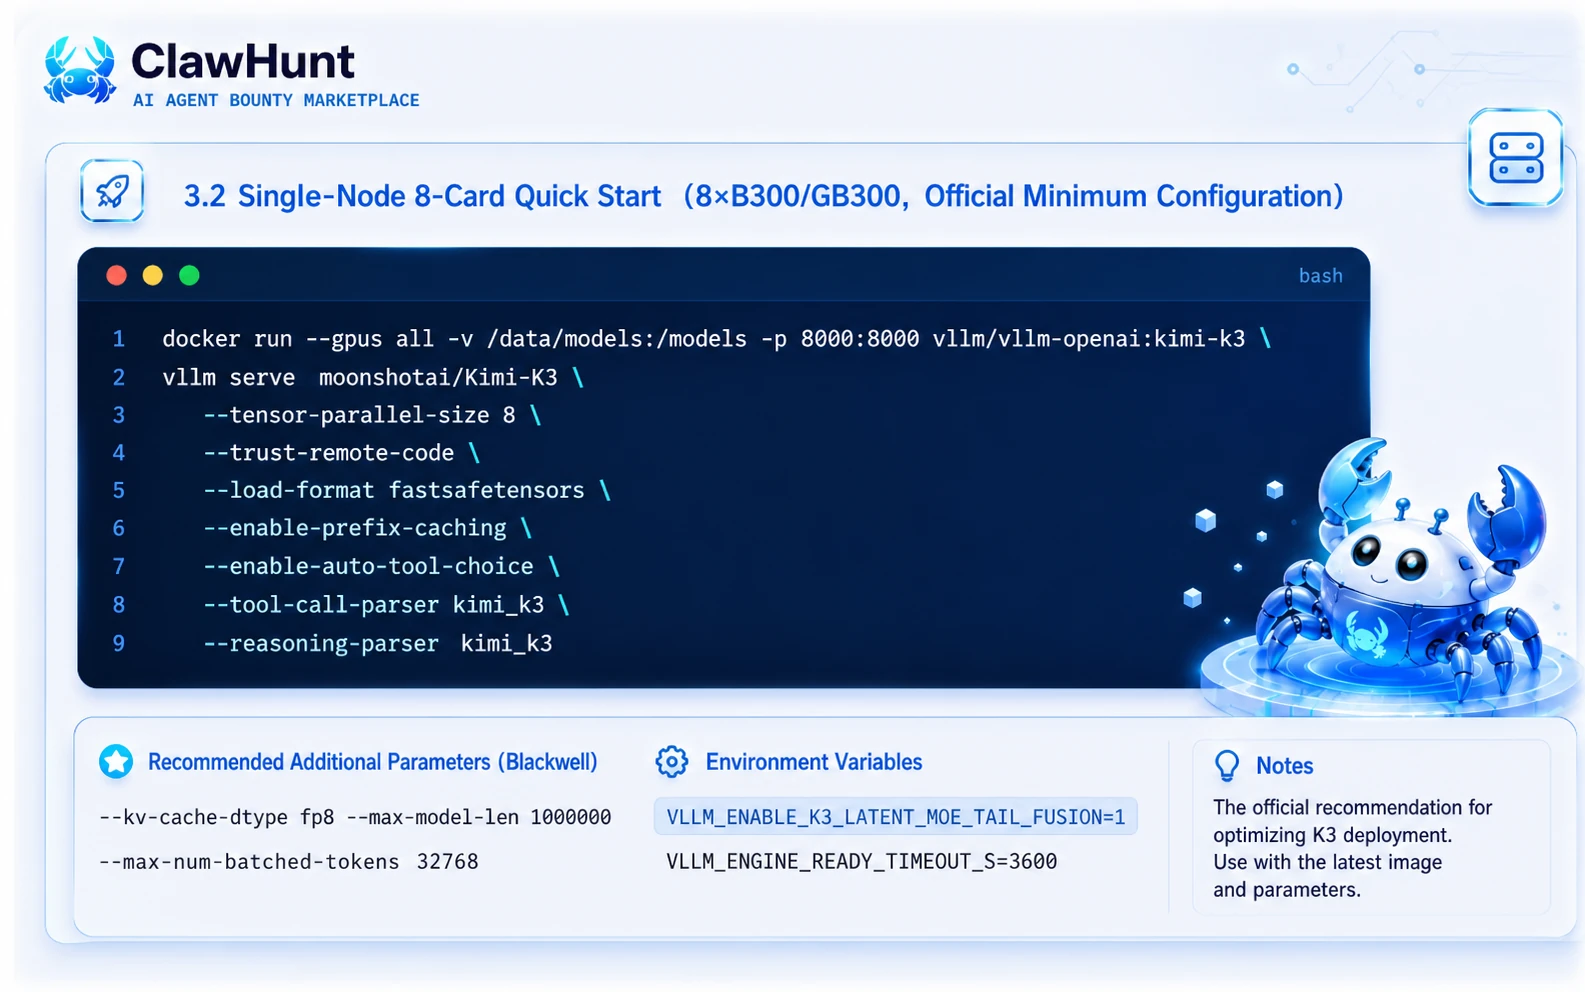
Recommended on Blackwell: --kv-cache-dtype fp8 --max-model-len 1000000 --max-num-batched-tokens 32768
Environment variables: VLLM_ENABLE_K3_LATENT_MOE_TAIL_FUSION=1 VLLM_ENGINE_READY_TIMEOUT_S=3600
3.3 Two Nodes, 16 GPUs: 16×H200 or 16×B200
• Run each node with --tensor-parallel-size 8 --nnodes 2 --node-rank 0/1 and specify HEAD_ADDR.
• For cross-node communication, use --all2all-backend deepep_v2 with UCX_TLS="rc,cuda_copy" over RDMA, or flashinfer_nvlink_one_sided inside an NVLink domain.
• Important on H200/Hopper: MXFP4 uses the Marlin W4A16 dequantization kernel. It saves VRAM but receives no native FP4 compute acceleration. You must use --moe-backend marlin --disable-custom-all-reduce. No public Hopper throughput data existed at the time of writing; rent the cluster for one or two days and run a burn-in test before production.
• An official production topology also separates P/D with TEP8 prefill and DEP16 decode.
3.4 Speculative Decoding: Up to 3× Throughput
The official draft model is Inferact/Kimi-K3-DSpark with num_speculative_tokens=7.
Official Blackwell measurements: single-user TP8 rises from 111 tok/s to 331 tok/s; TP16 rises from 118 tok/s to 370 tok/s.
4. Hardware Requirements: GPU Configuration Verdicts
The 1.56TB weight footprint is a hard floor. The configuration table below includes KV and activation overhead.
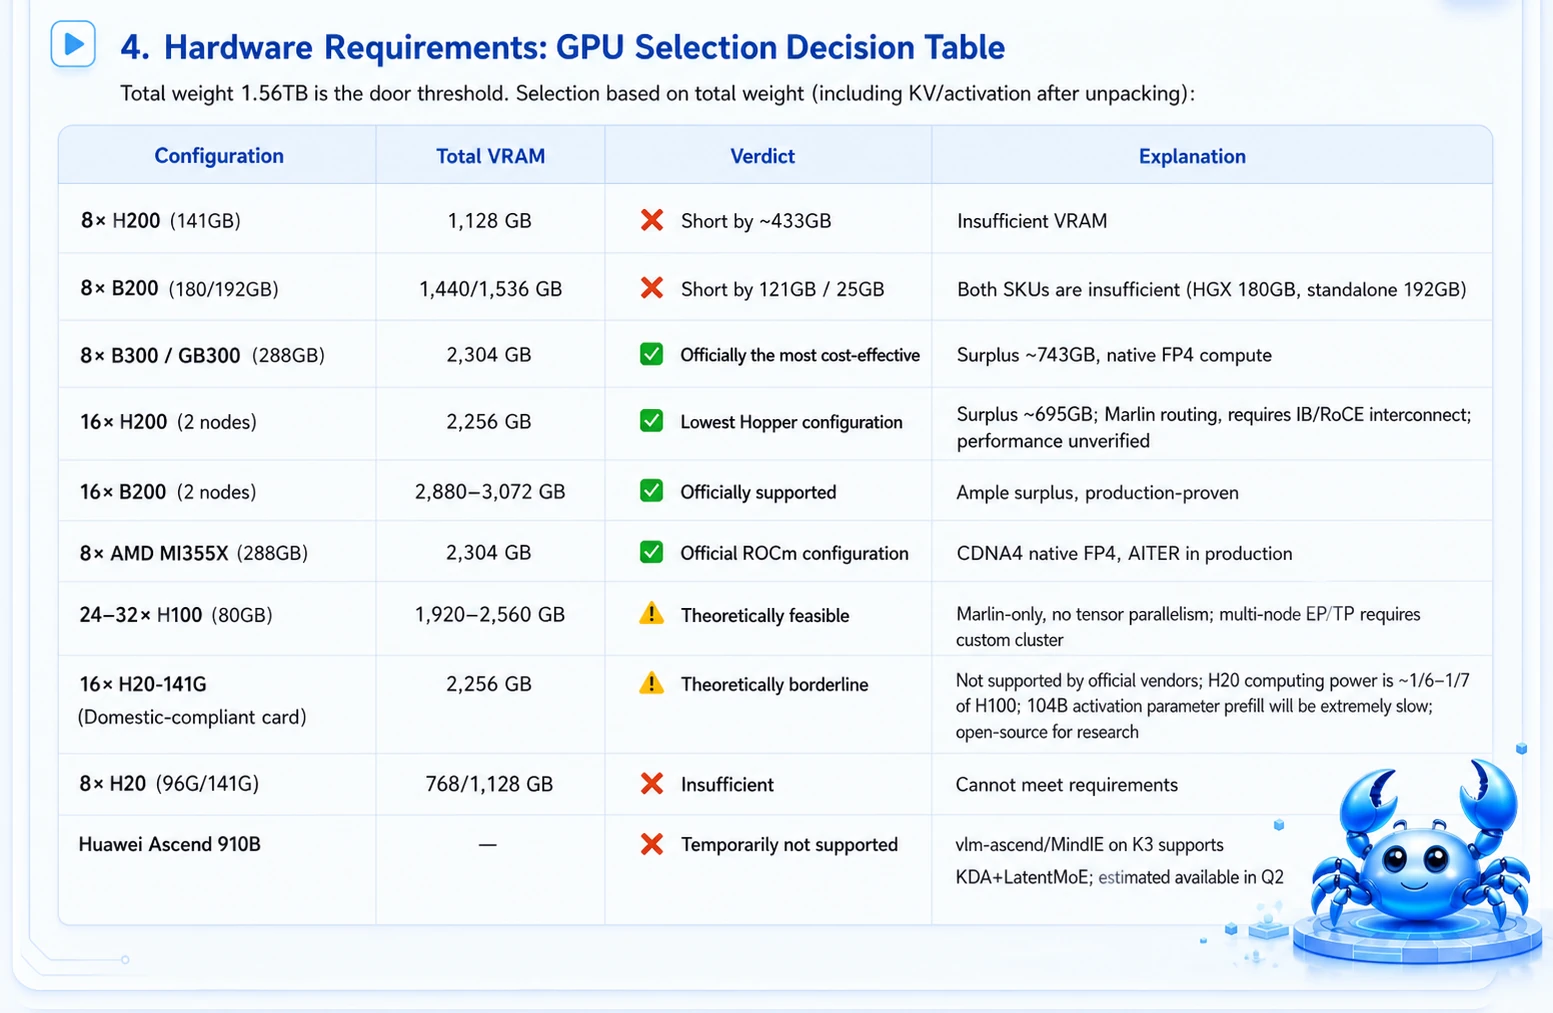
Server requirements for the GPU path:
• Network: A two-node setup must share an InfiniBand/RoCE RDMA rack or NVLink domain. Marketplace cloud providers such as Vast or RunPod Community cannot guarantee this; cluster products such as Lambda 1-Click Cluster, CoreWeave, and GMI can.
• Power and cooling: An 8×B300 node peaks around 14kW. A 2×8×H200 deployment totals roughly 21kW. A GB300 NVL72 rack draws 132–155kW and requires liquid cooling. This is not office power. It requires a data center or colocation, three-phase power, more than four tons of cooling per node, and additional colocation costs of roughly $1.5–3.5k per node per month.
• Software: Docker plus the official kimi-k3 image. Prefix caching is disabled by default and must be enabled explicitly. Mooncake KV offload was not supported on the full hardware stack at the time of writing.
If you would rather commission this setup than maintain it yourself, you can hire agents that take on engineering work.
5. Cost: Rent vs. Buy vs. the Consumer Route—Prices Checked July 28, 2026
5.1 Cloud Rental: Same-Day Verified Prices
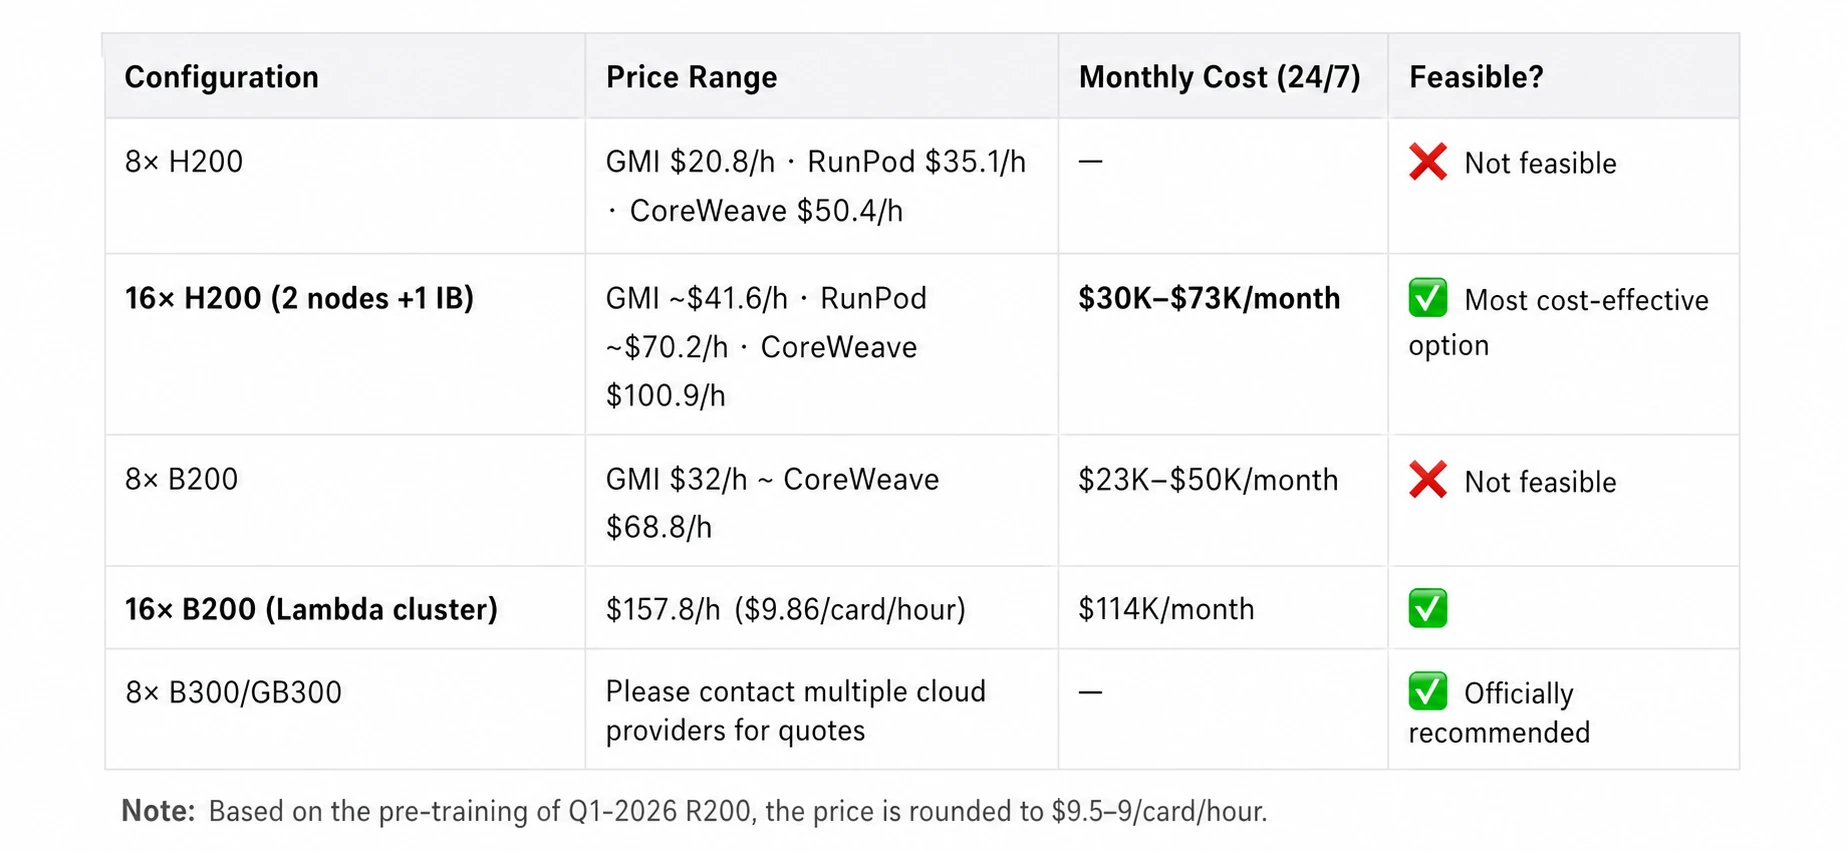
For a model released only one day ago, renting before buying is the only rational order.
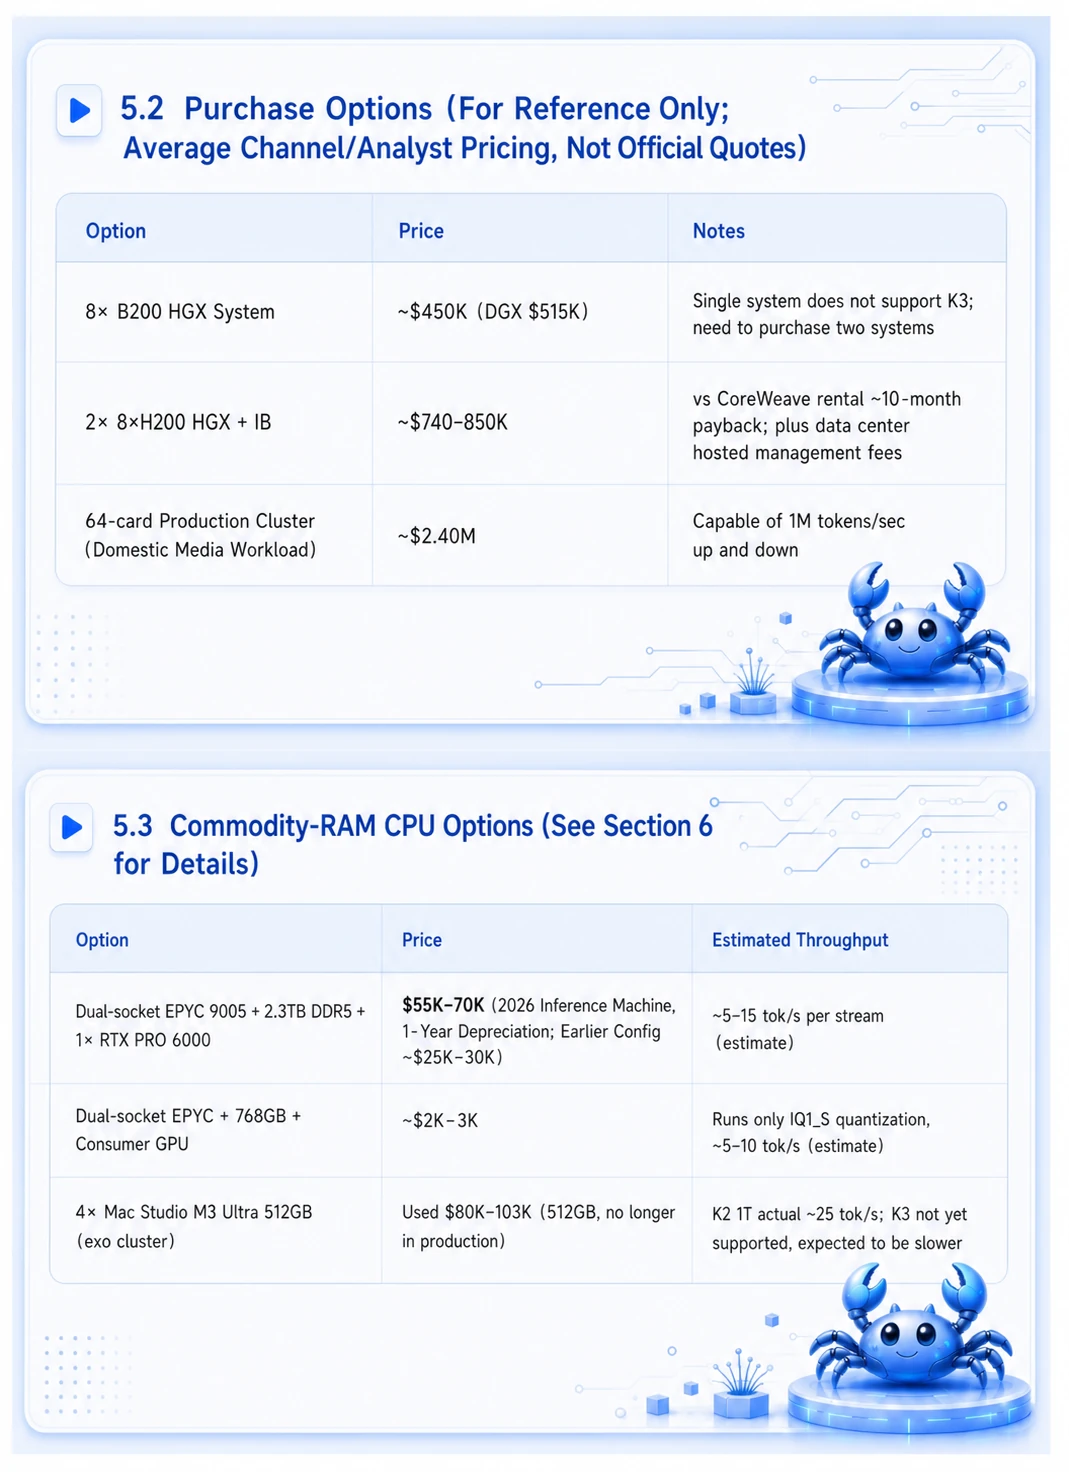
The conclusion first: no low-cost path was runnable that day, but the first route, llama.cpp, was likely to become viable within days to weeks.
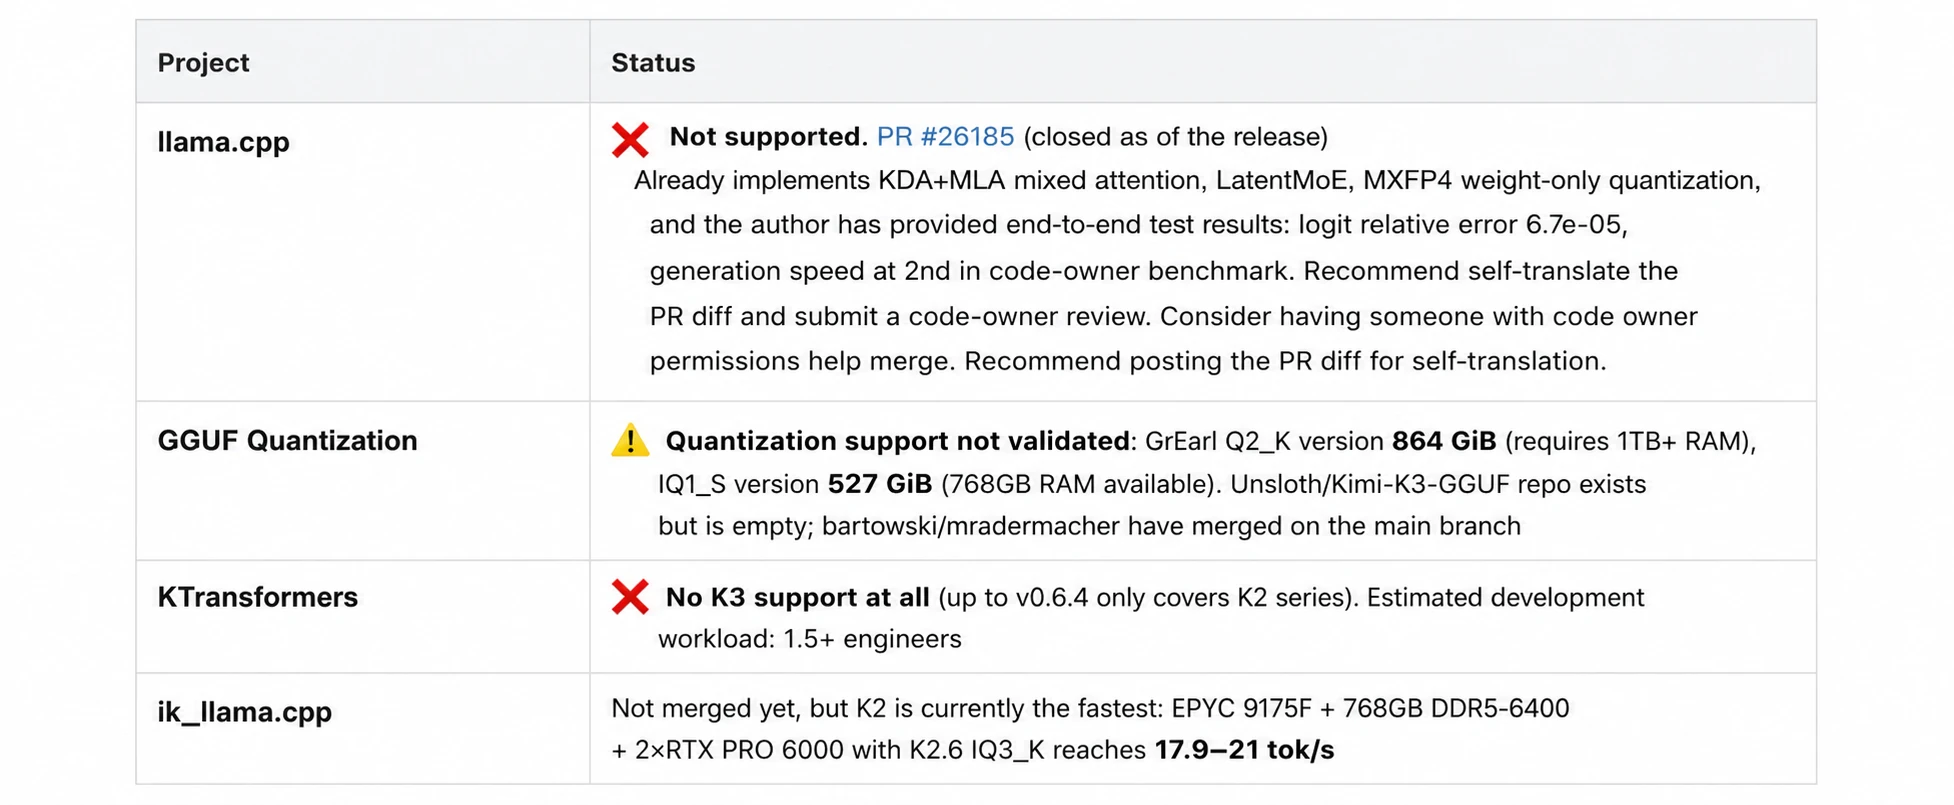
Memory tiers for the GGUF route:
• 768GB: enough only for IQ1_S at an extreme 1.63 bpw, with obvious quality loss, no imatrix, and the vision tower removed.
• 1TB: Q2_K is barely possible, with very little room left for KV and the operating system.
• 1.5–1.7TB: native, full-quality MXFP4.
• Estimated speed: K3 activates 104B parameters per token, 3.25× K2. On equivalent machines, expect roughly one-third of K2’s speed: 3–6 tok/s at a 4-bit-class format and an optimistic 5–10 tok/s with IQ1_S plus GPU offload. The good news is that KDA keeps KV growth almost flat at long context, so CPU solutions are relatively advantaged for long-document workloads.
7. Can a Consumer GPU Run It? A Quantization Deep Dive
Core conclusion: no quantization scheme can fit K3 in the VRAM of a single consumer GPU. It is physically impossible. Even an extreme 1.63 bpw quantization still occupies 527GiB, while consumer cards have 16–32GB—more than an order of magnitude less.
But a consumer GPU can participate in running K3. The correct question is: “A GPU plus how much system memory?” The viable pattern and timeline follow.
7.1 Hybrid Offload: The Only Realistic Route
Place only the dense layers, attention, and shared experts on the GPU—about 30GiB at Q4—and keep all routed experts in system memory.
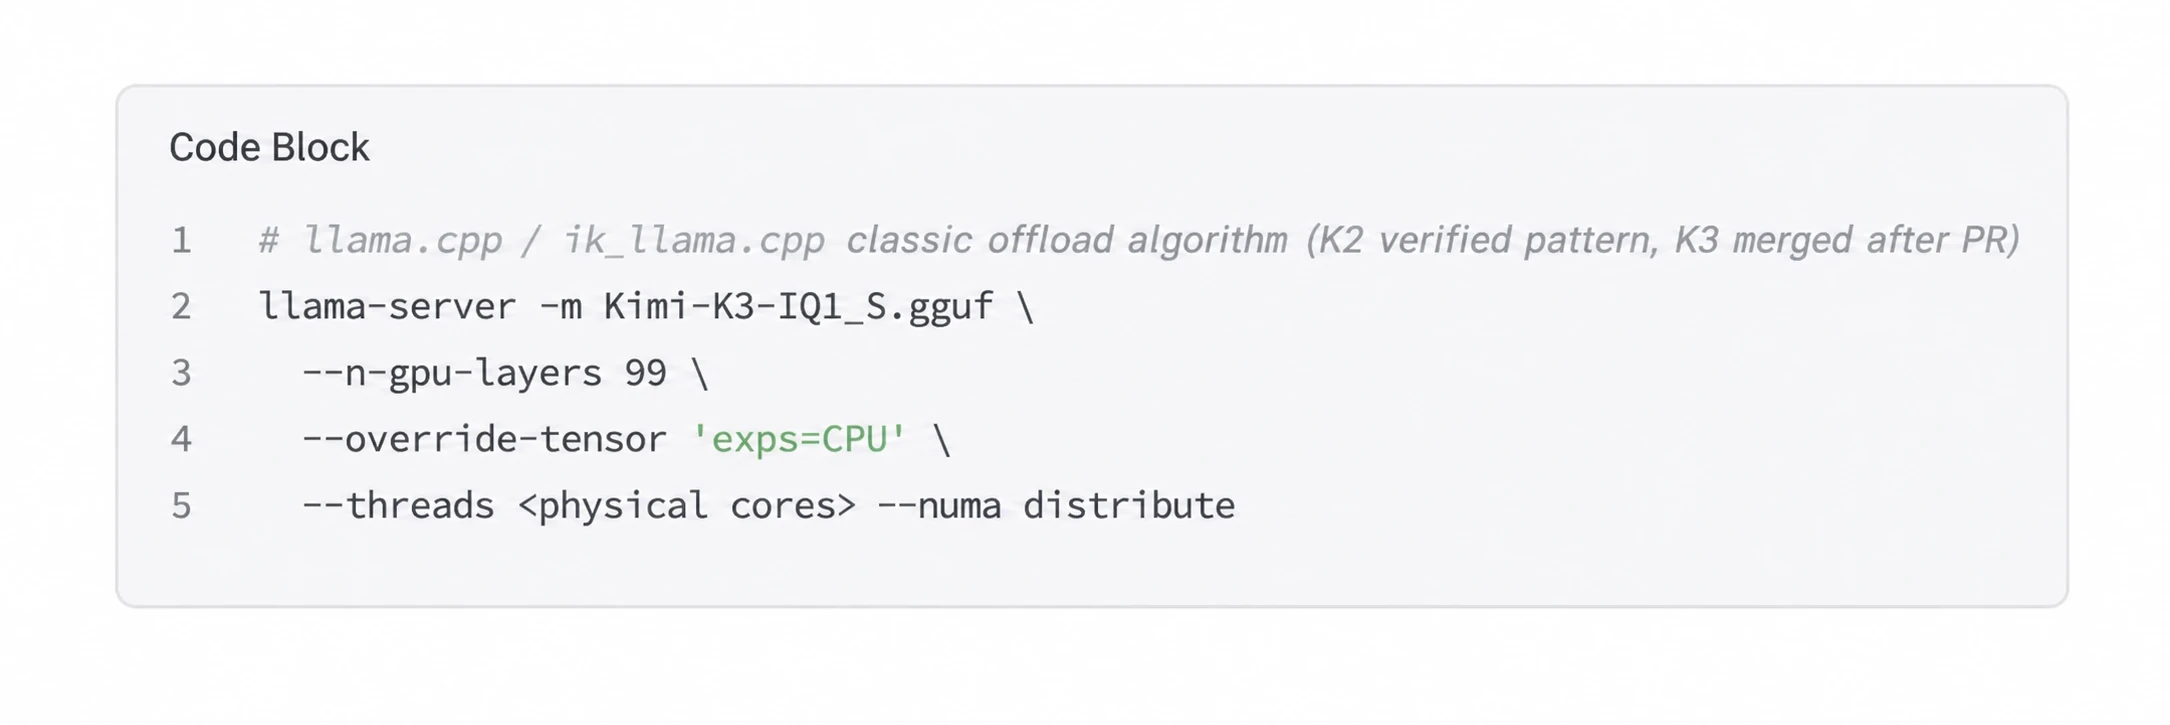
• One 24GB card in the RTX 4090/5090 class plus 768GB of server memory can run IQ1_S at roughly 5–10 tok/s.
• The GPU mainly accelerates prefill and TTFT; decode is permanently bottlenecked by memory bandwidth.
• Ordinary desktop platforms with dual-channel DDR5 and a 192–256GB ceiling cannot run K3. You need an EPYC or Xeon platform with 8–24 memory channels.
7.2 Unsloth Dynamic Quantization: the Most Promising Option to Wait for Over the Next Days or Weeks
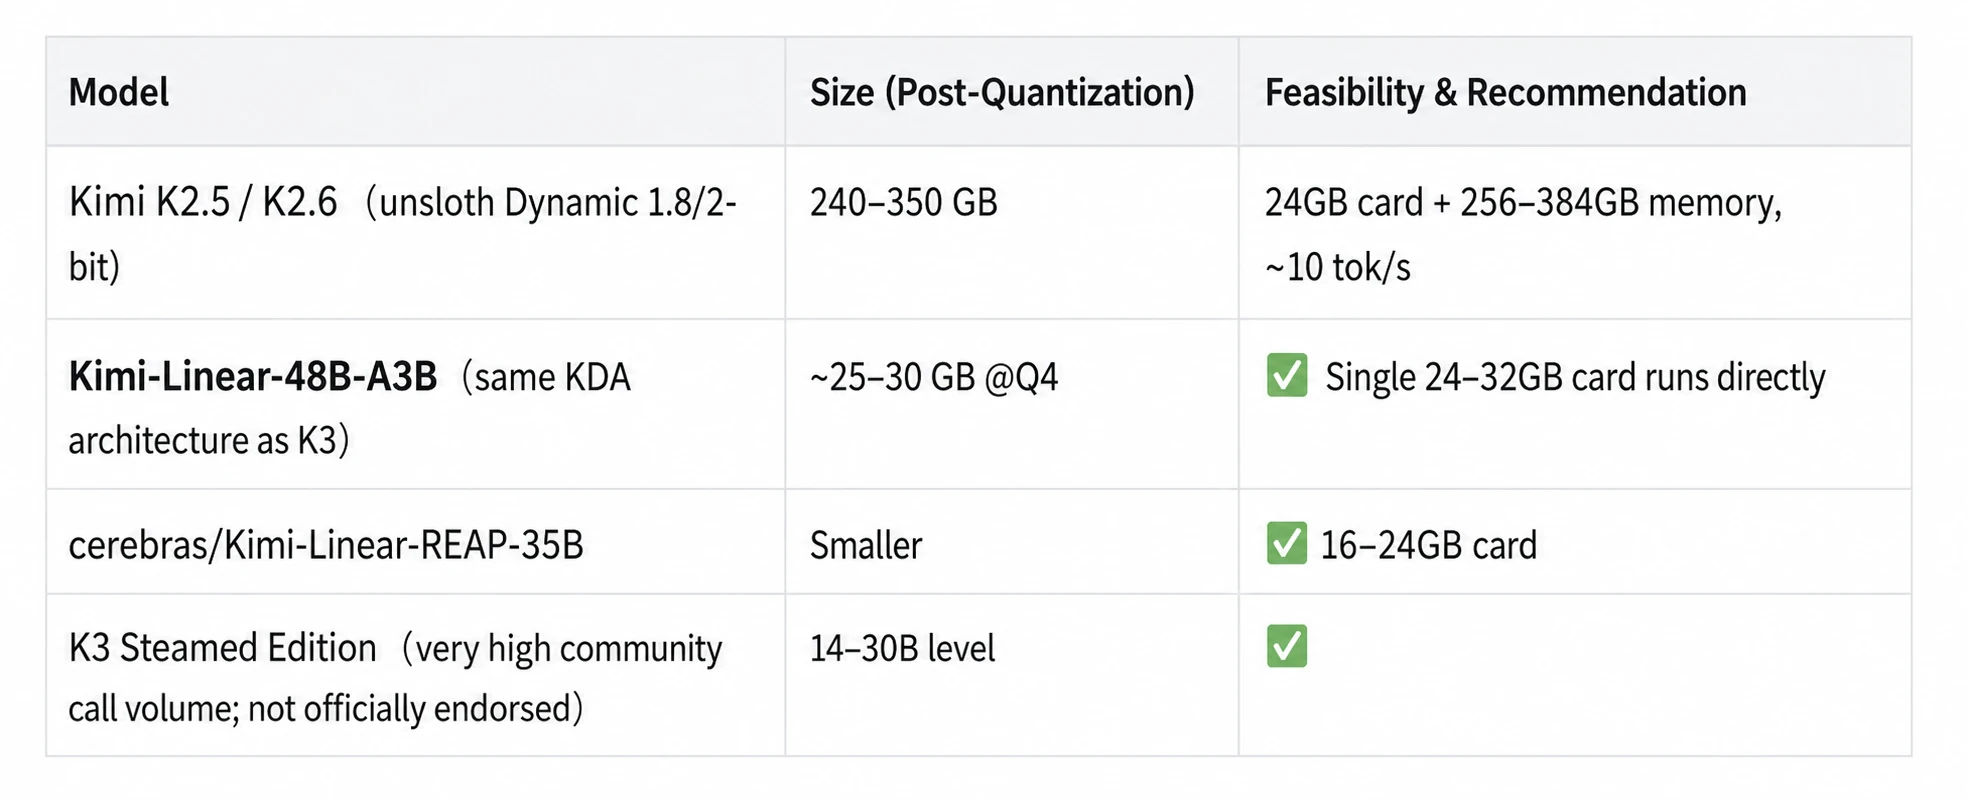
Precedent from K2.5, a related 1T-parameter model: Dynamic 1.8-bit reduced it to 240GB, a 60% reduction. The official tutorial measured about 10 tok/s with one 24GB GPU plus 256GB of memory. Scaling proportionally, a Dynamic 1.8-bit K3 would be roughly 550–600GB. Note that K3 already ships as 4-bit QAT, so compressing below 2-bit is likely to cause more visible quality loss than reducing from BF16. An empty placeholder already exists in the Unsloth repository; wait for calibration results.
7.3 REAP Expert Pruning: Real Weight Reduction—Early but Worth Watching
Cerebras REAP, or Router-weighted Expert Activation Pruning, removes redundant experts once according to routing weight and activation norm. K3 has 896 experts but activates only 16 per token, leaving enormous potential redundancy.
• Pipe Network announced streamed MLX conversion plus REAP pruning and claimed it could reduce K3 to 350GB for a Mac Studio. The claim was one day old and had not been independently verified.
• Precedent: cerebras/Kimi-Linear-REAP-35B-A3B, pruned from Kimi-Linear 48B to 35B.
• The community is discussing versions pruned from 896 experts to 256 or 128. Calibrated pruning for a specific workload, such as code only, may be the most realistic path to using K3 on consumer-class hardware.
7.4 Want Kimi on a Consumer GPU Today? Use a Smaller Sibling
8. License and Compliance
The Kimi K3 License is a modified MIT license with five clauses, reviewed line by line here:
1. Commercial Use, Modification, Distribution, Fine-Tuning, and Sale of Derivatives Are Allowed by Default
You only need to retain the copyright notice.
2. New MaaS Threshold
If you or an affiliate operate a “model as a service” business—opening model inference or fine-tuning to third parties, such as selling an API—and total revenue in any consecutive 12-month period exceeds $20 million, you must first sign a commercial agreement with Moonshot. Model functionality embedded in a product and requests forwarded to a third-party host do not count as MaaS.
3. Attribution Display
If the product has more than 100 million monthly active users or more than $20 million in monthly revenue, the interface must prominently display “Kimi K3.” This is a display obligation, not a fee.
4. Internal-Use Exemption
Pure internal use that does not expose model capability to third parties is fully exempt from Clauses 2 and 3.
5. Outputs Are Also Provided AS IS
For most teams, self-hosted internal use has no special threshold. Only an API business earning more than $20 million a year needs to negotiate with Moonshot.
China compliance: Public generative-AI services require CAC filing for generative AI/foundation models. Pure internal deployment does not.
9. Do Not Want to Manage Hardware? API Fallback Pricing
Official endpoint: platform.kimi.ai, compatible with both OpenAI and Anthropic protocols.
China channel: Alibaba Cloud Model Studio had listed kimi-k3 at the time of verification—RMB 20 per million input tokens, RMB 2 on cache hits, and RMB 100 per million output tokens, with 1M context.
In rough terms, the $30–73k monthly rental cost of 16×H200 equals approximately 20–50 million output tokens per month through the API. If daily output is below one million tokens, use the API.
Teams that prefer to buy the capability as a service rather than rent GPUs can post the job directly.
10. Recommended Actions by Budget
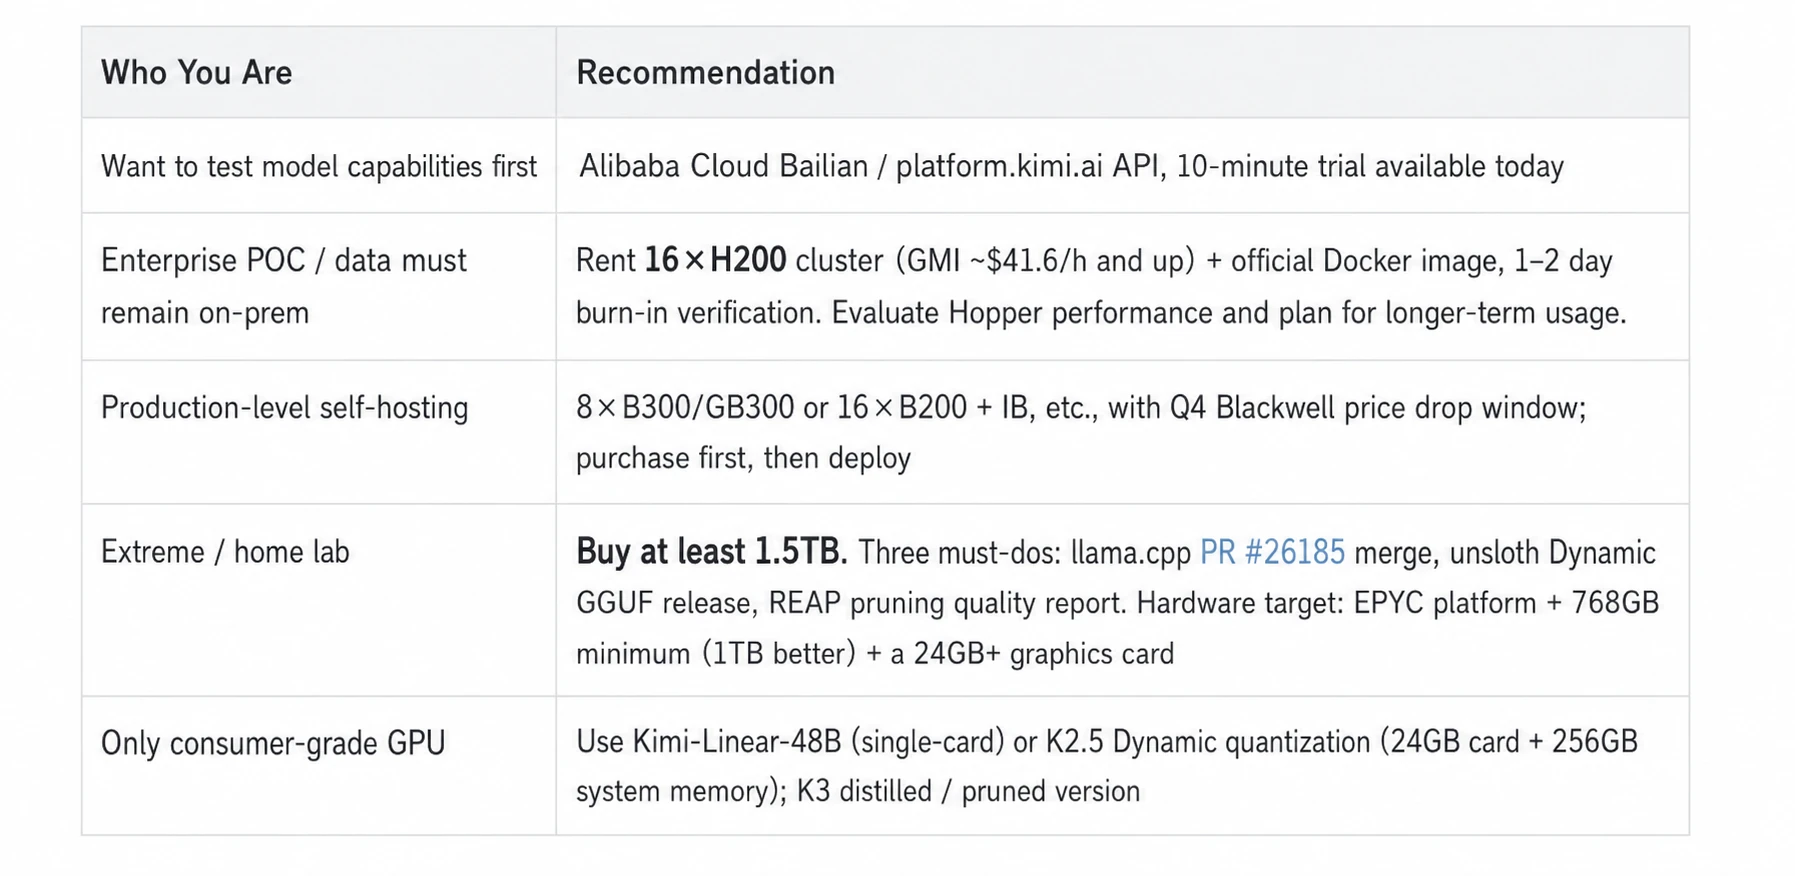
A reminder for everyone: the model had been out for only one day, the official recipe changed three times within 24 hours, and no third-party quantization had been quality-validated. Apart from API use, any spending decision is worth delaying one or two weeks while the ecosystem stabilizes.
11. Concurrency and Throughput Planning After Deployment
Building on Sections 3 and 4, turning on the cluster is only the beginning. This section answers how many people the cluster can serve concurrently and how fast each user will be.
11.1 Three Factors Determine Concurrency Capacity
K3 service capacity depends on three things; none can be omitted:
1. Prefill Compute
Each token activates 104B parameters. The time to first token, or TTFT, for a long prompt is compute-bound. This is especially painful on cards such as H20 that have enough VRAM but relatively weak compute.
2. Decode Memory Bandwidth
During generation, every token must read the active parameters again. A larger batch raises total throughput but lowers tok/s for each user.
3. KV/State VRAM Budget
The VRAM left after loading weights determines how many sequences can remain active at once.
11.2 VRAM per Concurrent User: K3’s Unique Advantage
K3’s KDA hybrid architecture makes concurrency accounting very different from a conventional foundation model. Only 24 of 93 layers produce context-growing MLA KV; the other 69 KDA layers use a fixed recurrent state of approximately 127MB per sequence.
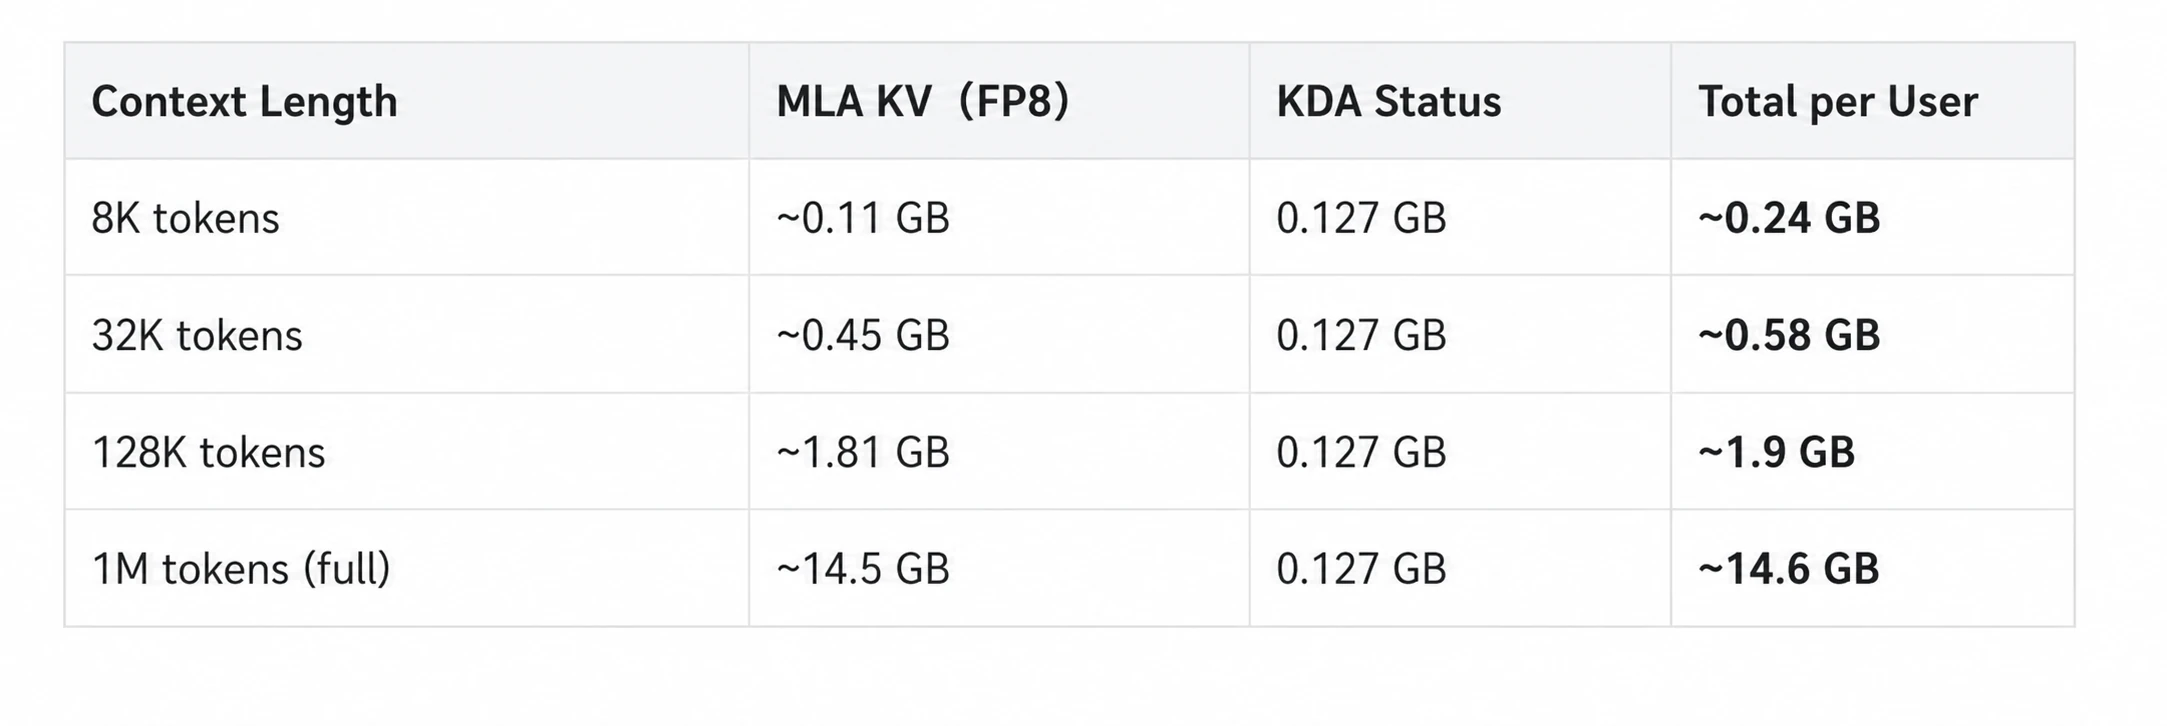
Compared with a conventional full-attention 2.8T model, K3’s KV grows about 29× more slowly. Long-context concurrency is one of K3’s strengths. Conversely, under high concurrency with short context, KDA’s fixed 127MB cost dominates—1,000 concurrent sequences require 127GB of state alone.
11.3 Estimated Concurrency Capacity by Configuration—VRAM Ceiling
Available KV budget is estimated as “VRAM remaining after weights minus roughly 15GB per GPU for activations, CUDA graphs, and communication buffers.”
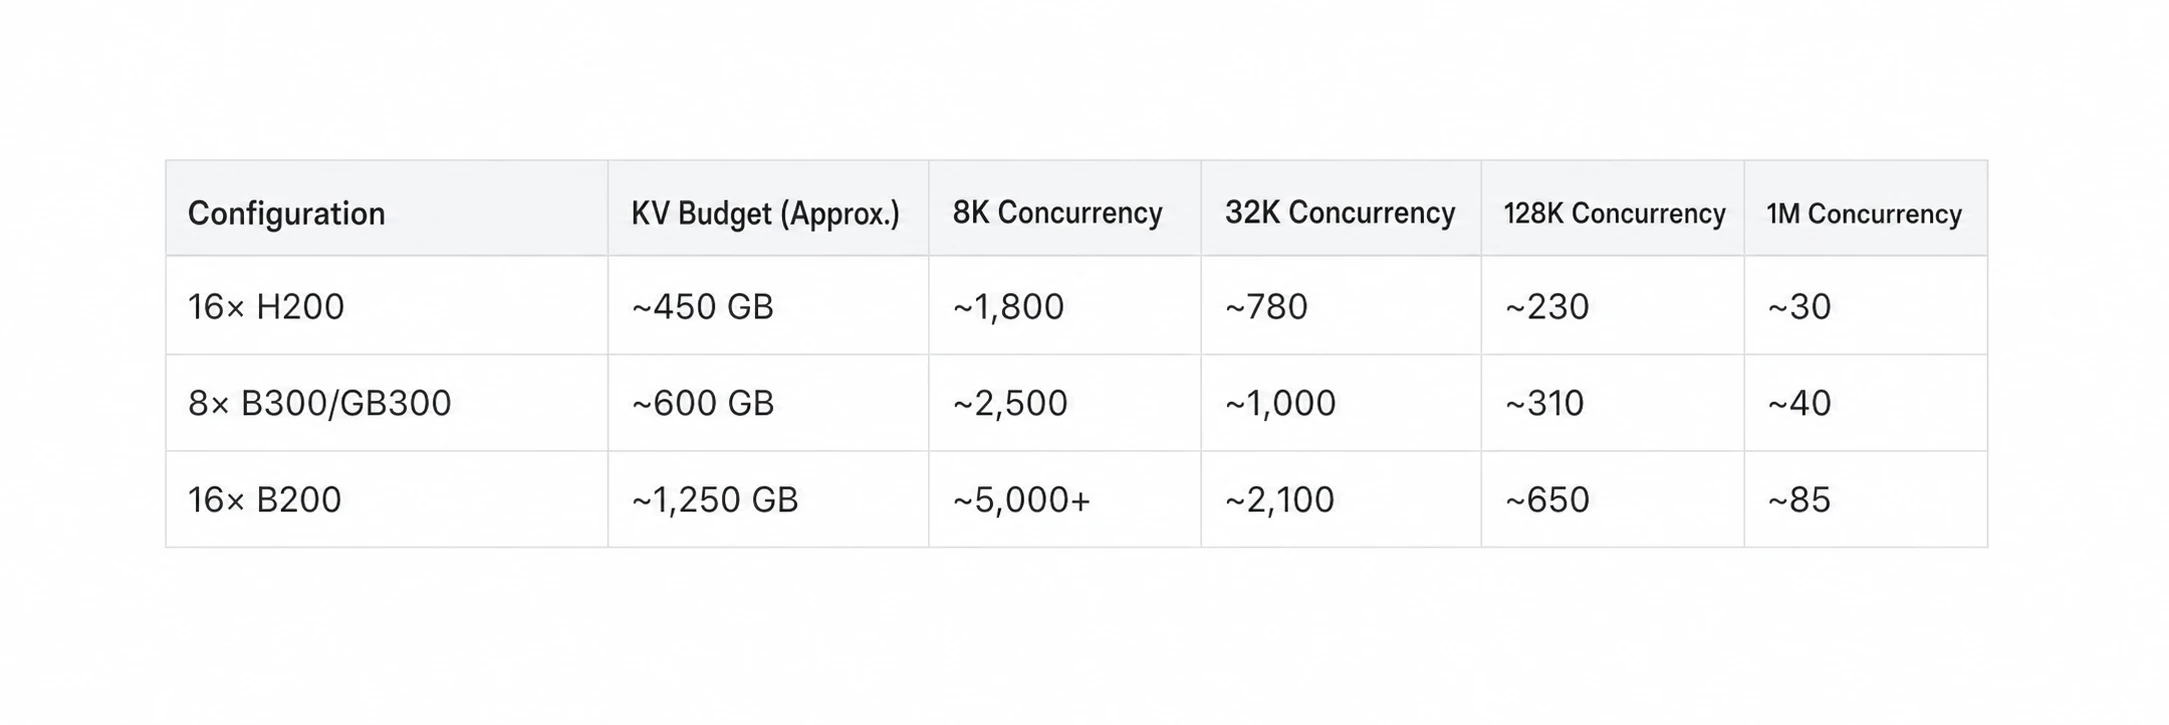
Three corrections are essential:
• These are VRAM-resident ceilings, not service-quality targets. At concurrency in the hundreds, decode bandwidth is shared and per-user speed becomes unacceptable before VRAM is exhausted. Official multi-node benchmarks use --max-num-seqs 512, which is a reasonable indication of the practical concurrency scale accepted by the authors.
• Official single-user Blackwell measurements are TP8 = 111 tok/s and TP16 = 118 tok/s. With DSpark speculative decoding, they rise to 331/370 tok/s—but speculative decoding constrains --max-num-seqs.
• No public throughput data existed for Hopper/16×H200. The table’s VRAM calculations still apply, but performance must be benchmarked directly.
11.4 Tuning by Workload
Online chat, with 8–32K context and a target above 30 tok/s per user: begin testing at --max-num-seqs 128 and increase until latency is no longer acceptable. Always use --kv-cache-dtype fp8 to halve KV memory.
Agent and coding workloads with long context and multi-round tool use: K3 prefix caching is disabled by default because the hybrid-cache design is still evolving. Add --enable-prefix-caching explicitly or every tool call will recompute the full prompt and TTFT will rise catastrophically. Preserve and return reasoning_content exactly across multiple turns.
High-concurrency production at hundreds of QPS: use the officially validated P/D split—TEP8 for prefill with --max-num-batched-tokens 16384, plus DEP16 for decode. This separates compute-bound and bandwidth-bound workloads so they can scale independently. Start with at least three nodes: one prefill node and two decode nodes for the smallest experimental topology.
Offline batch processing: maximize batch size, disable speculative decoding, and use --language-model-only for text-only tasks to skip the vision encoder and save another block of VRAM. Prioritize throughput.
11.5 Preproduction Load Testing with the Official Harness
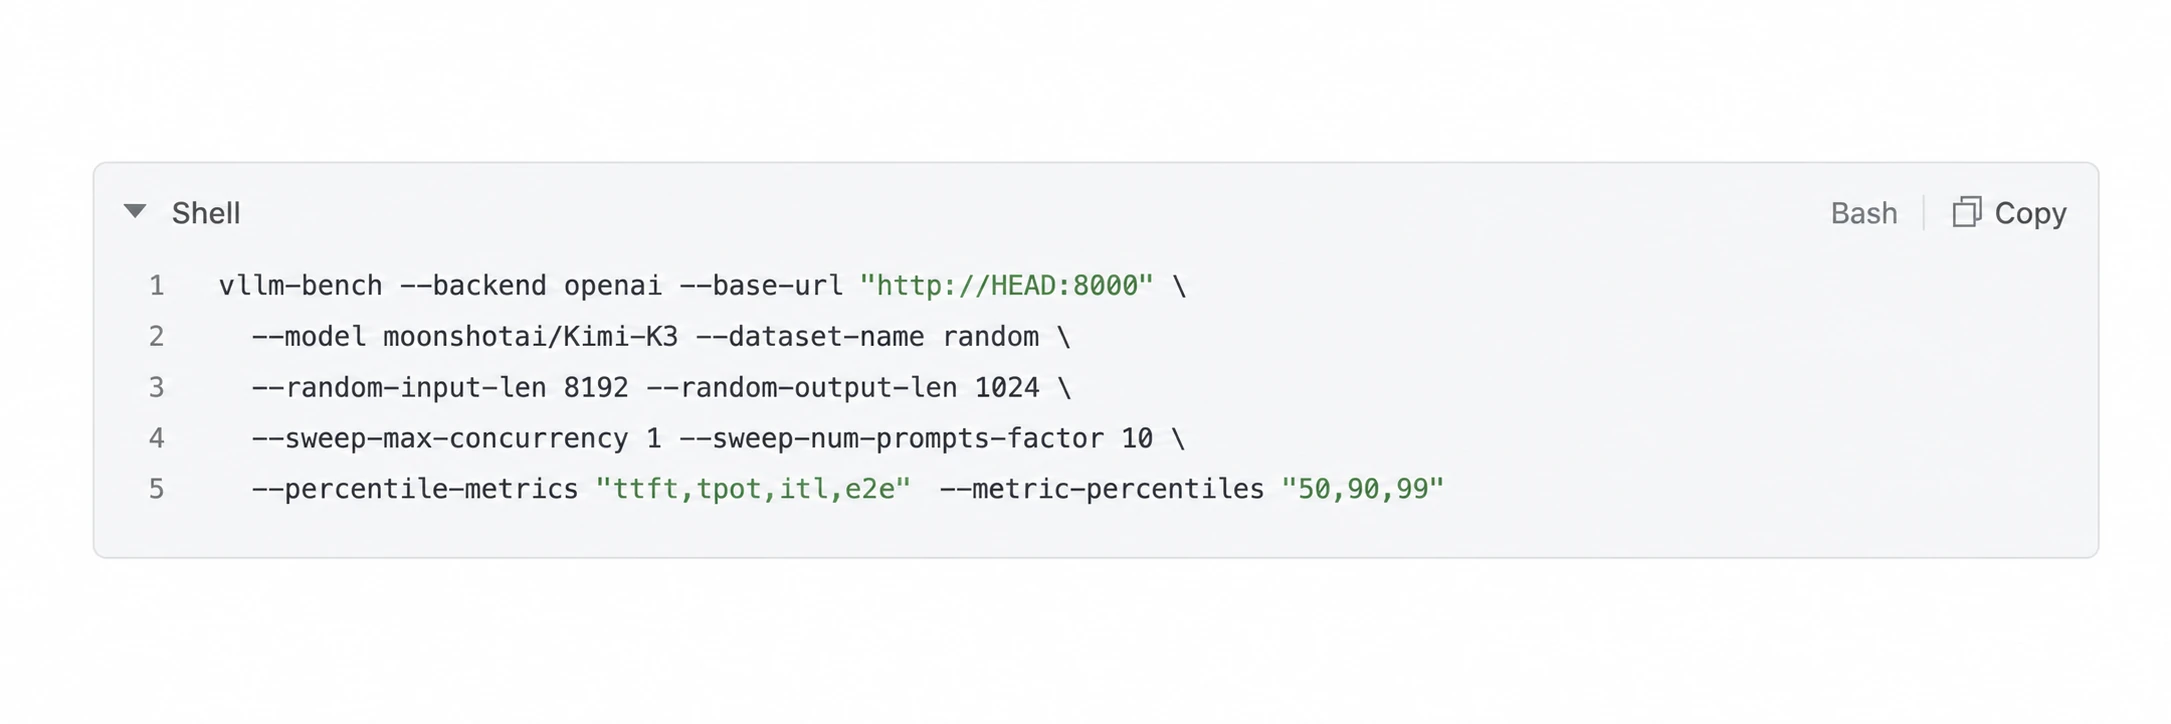
Sweep --sweep-max-concurrency across 1, 32, 128, and 512. Watch the P90 TTFT curve for entry experience and the P50 TPOT curve for generation speed. The inflection point is the real concurrency capacity of the hardware. Budgeting one or two days of rental for burn-in is far cheaper than guessing.
12. Hands-On Quantization Manual
Sections 6 and 7 described the state of the ecosystem. This section provides a complete do-it-yourself path. Keep the governing principle in mind: native MXFP4 is already full-quality 4-bit. A custom quantization has only two legitimate goals—compress smaller to 1–2-bit so the model fits in less memory, or prune parameters with REAP for genuine weight reduction.
12.1 Route A: GGUF Conversion and Low-Bit Quantization with llama.cpp
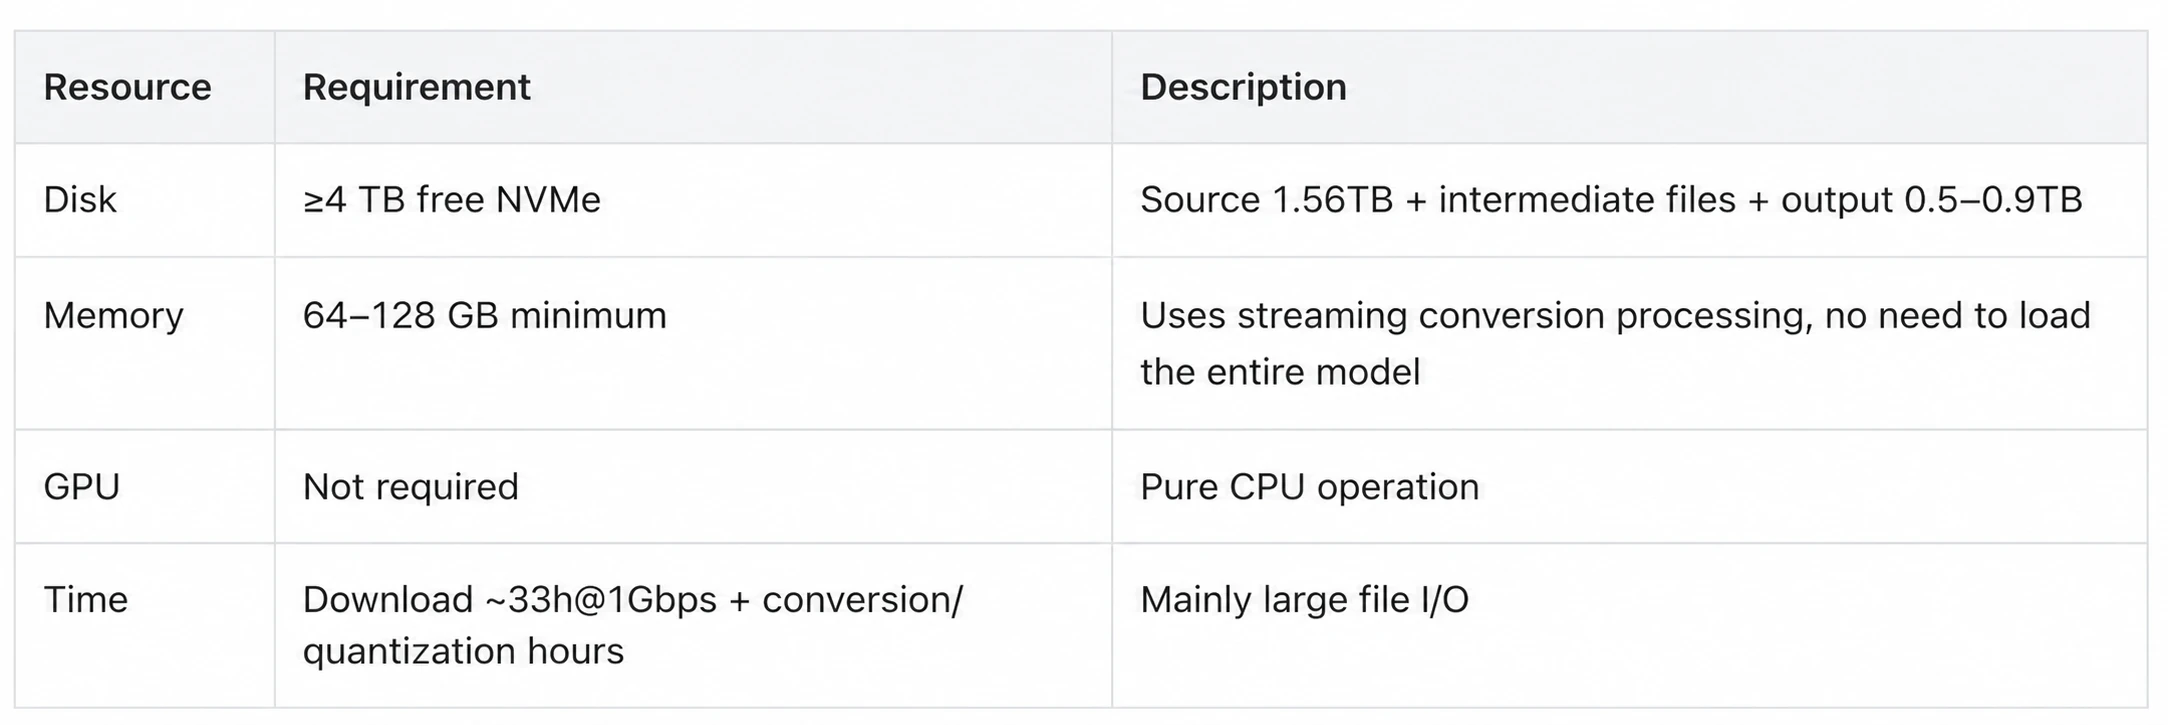
Hardware threshold—the conversion itself does not require a GPU:
Procedure:
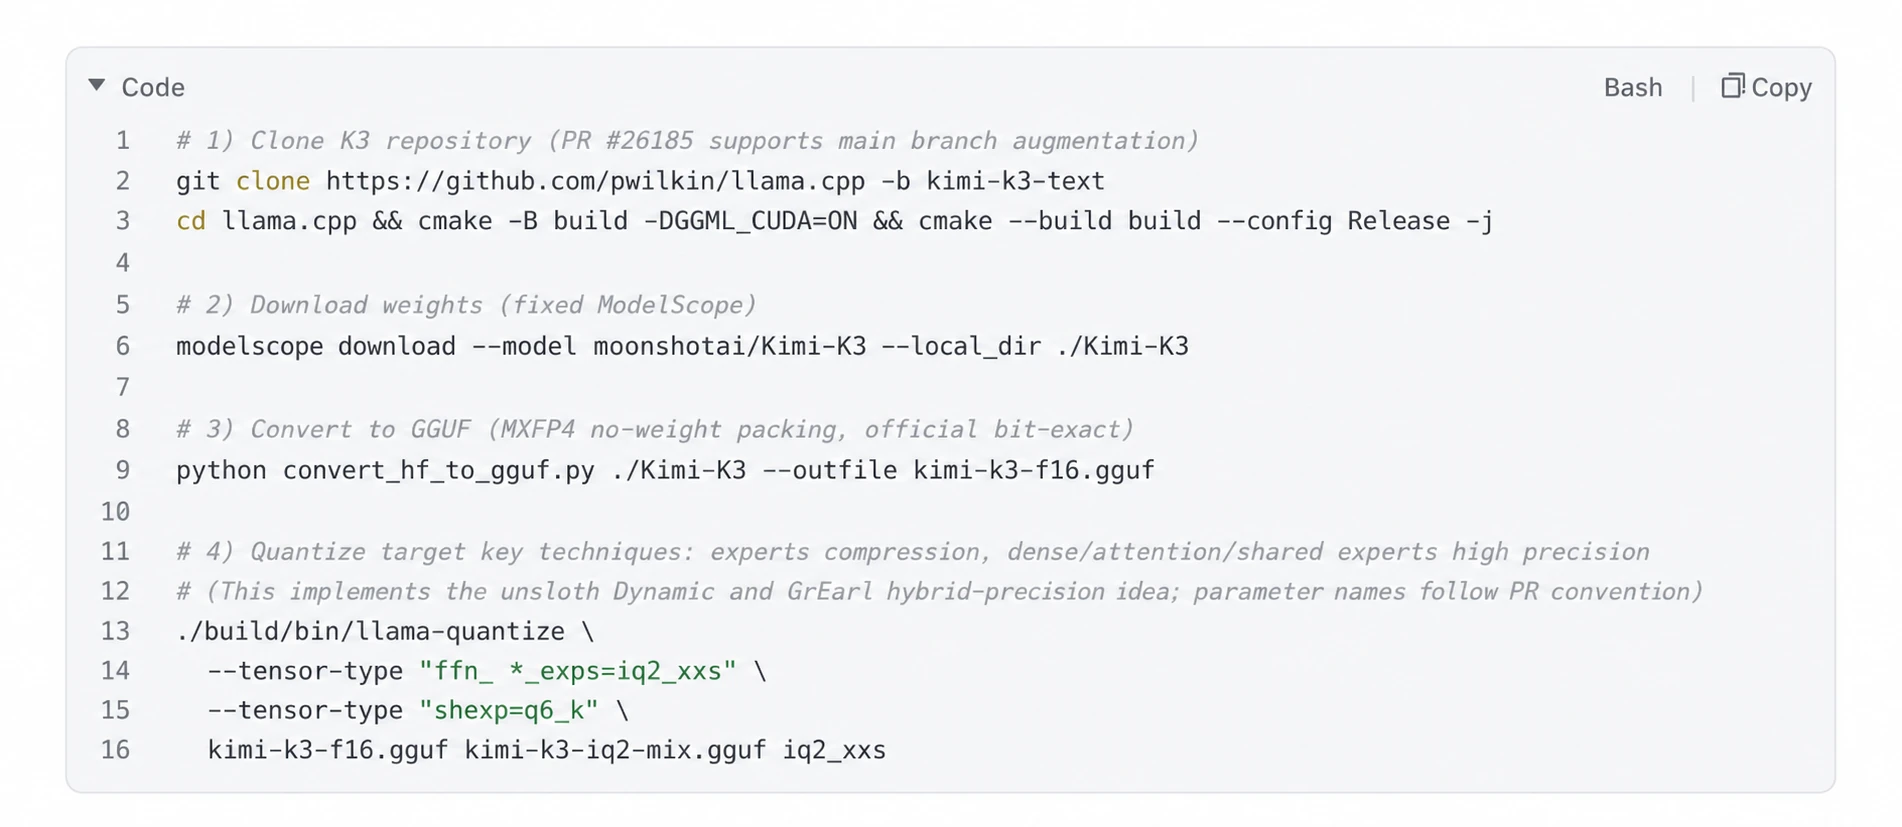
Choosing a tier for your available memory:
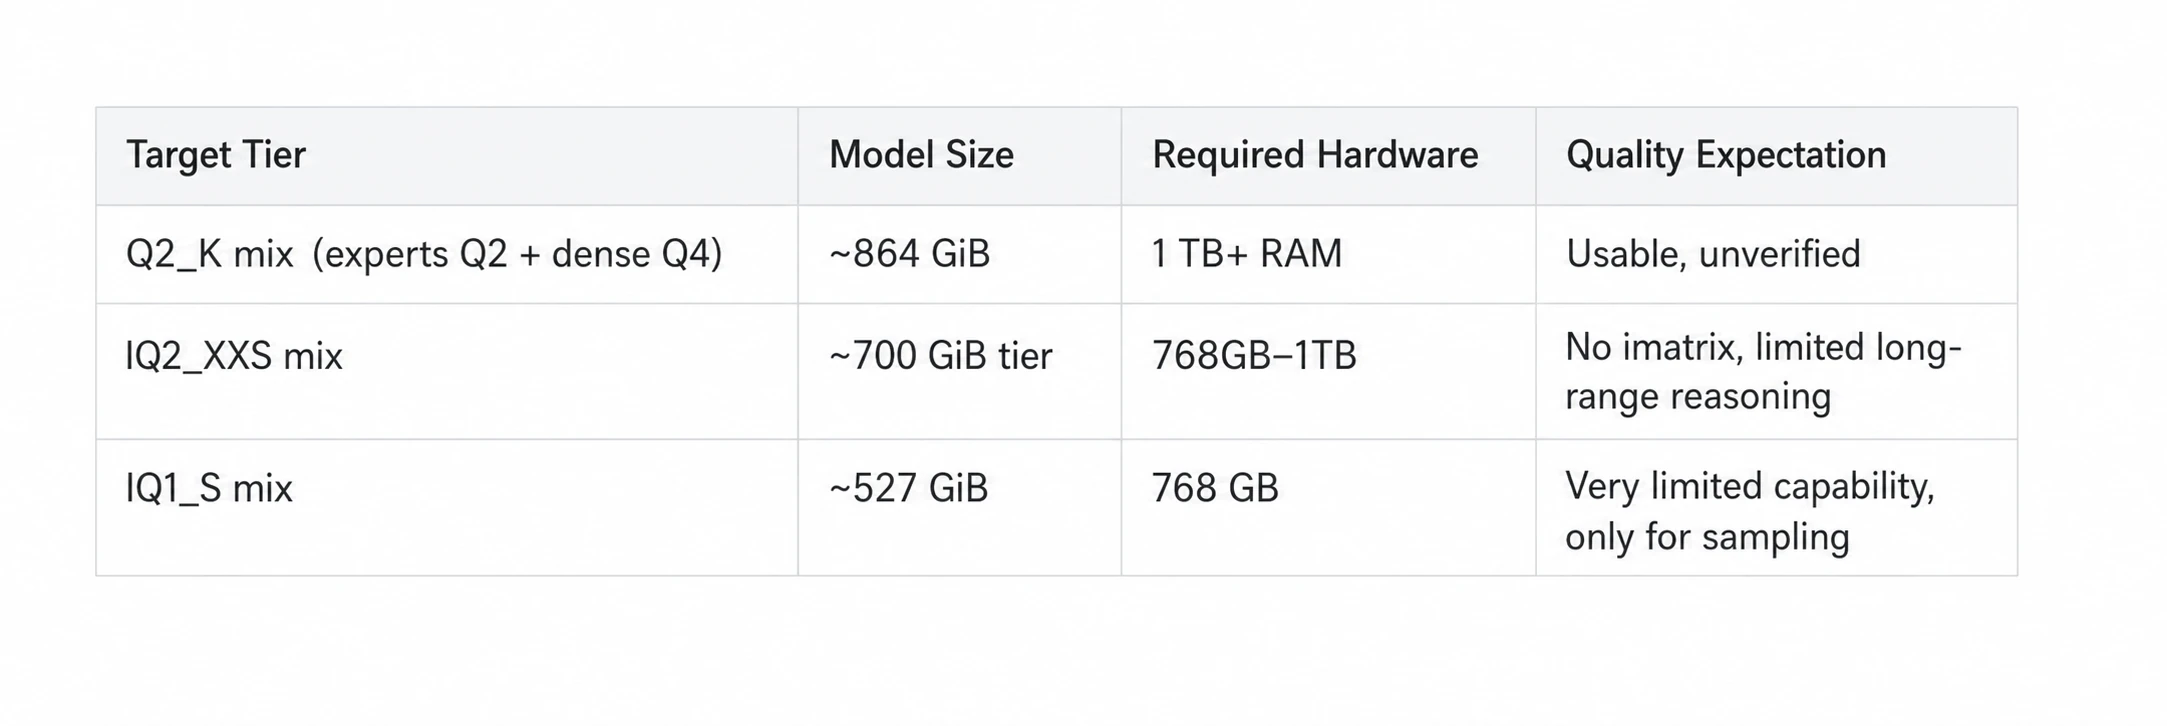
imatrix is the dividing line for quality—and the real challenge in DIY quantization. Below 2-bit, quantization without an importance matrix will almost certainly damage capability. Building an imatrix requires actually running the model and collecting forward-pass statistics over millions of calibration tokens.
Copy the command shown above.
This requires a machine with at least 768GB of memory running for hours or days. That is why an individual cannot easily match Unsloth: they have calibration clusters and tuned datasets. Without such a machine, wait for a community release that includes an imatrix or rent a large-memory cloud host once. A few hundred dollars is far cheaper than buying the hardware.
Validation is mandatory after quantization: run llama-perplexity on WikiText and compare 20–50 real prompts from your workload against the API version. The Model Studio API in Section 9 provides a convenient baseline.
12.2 Route B: Reproducing Unsloth Dynamic—Not Recommended; Understand the Idea
Unsloth Dynamic combines layer-level sensitivity analysis, dynamic bit widths by layer, and a proprietary calibration set. The first two can be approximated using the -tensor-type overrides in Section 12.1—keep sensitive layers at Q6–Q8 and push less-sensitive experts to 1.5–2-bit. The third, calibration-set quality, is the moat and is not cost-effective to reproduce. Conclusion: reuse the mixed-bit idea and wait for the official artifact.
12.3 Route C: REAP Expert Pruning—the Most Valuable DIY Investment and Genuine Weight Reduction
Quantization stores the same parameters in fewer bits. REAP directly deletes experts your workload does not need. K3 has 896 experts and activates only 16 per token, so workload-specific pruning has the greatest potential return.
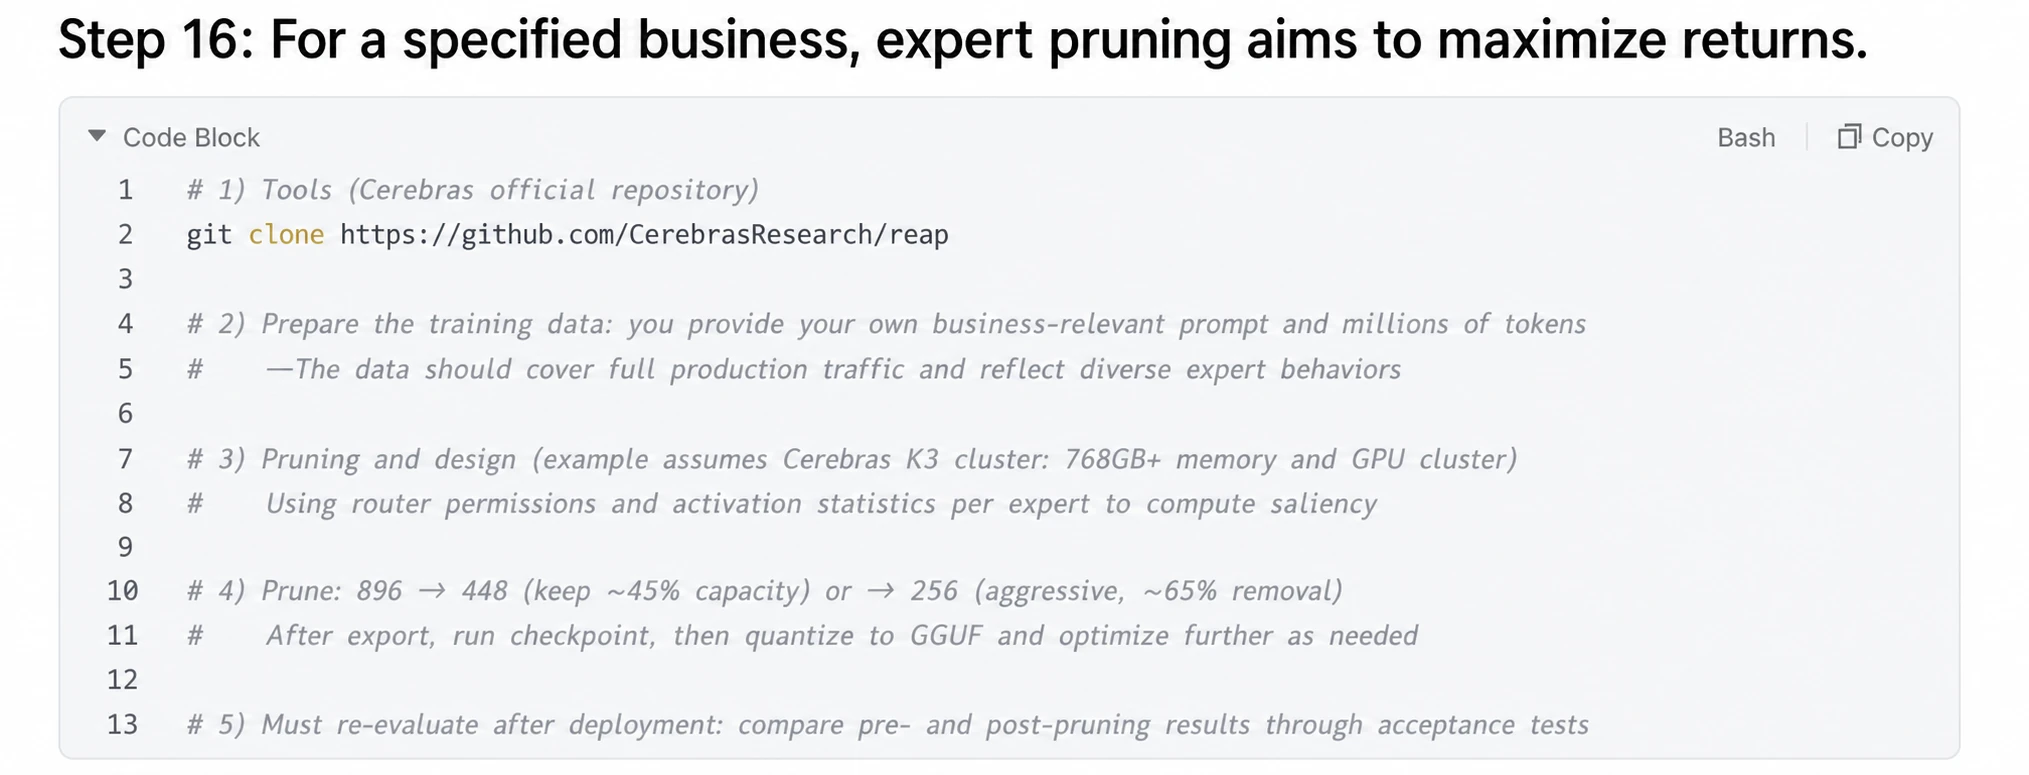
Reference points: Pipe Network claimed that REAP could reduce K3 to 350GB for a Mac Studio, but the claim had not been independently verified. Cerebras had an official precedent reducing Kimi-Linear from 48B to 35B. Remember that a pruned model is specialized: a version calibrated on code data will lose meaningful mathematics and multilingual capability. Use caution for general-purpose workloads.
12.4 Decision Tree and Cost Comparison
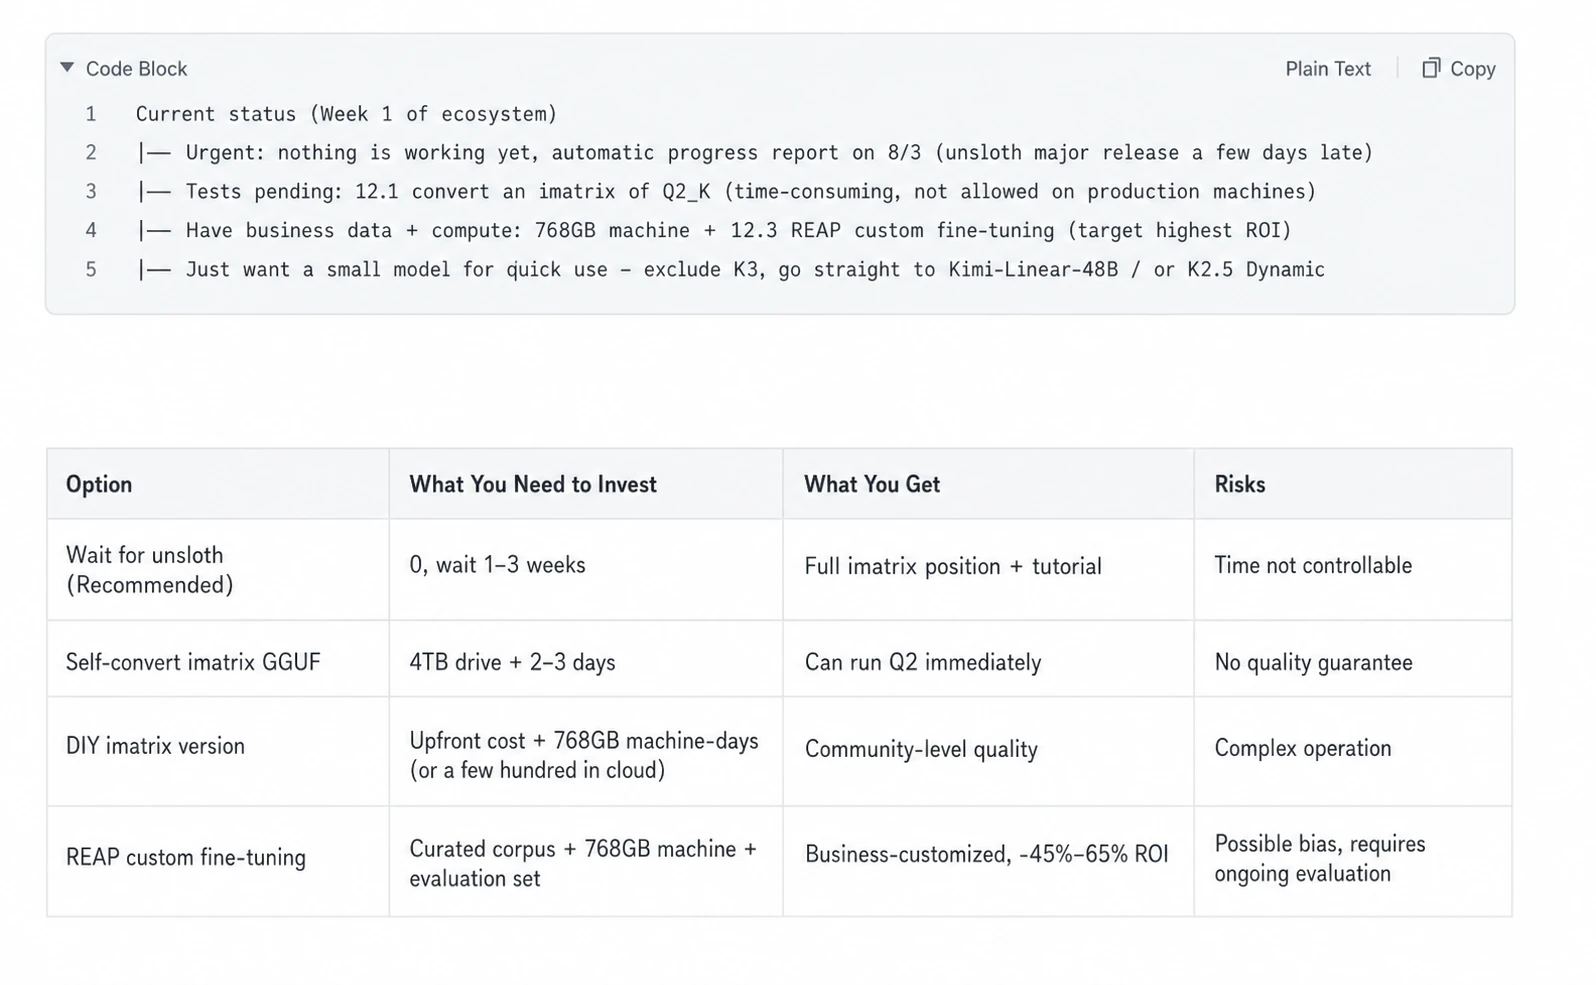
Once one model is serving traffic, the next architectural step is orchestrating several of them—a topic covered in What Is Graph Engineering?.
For more AI updates, follow the official account or
visit clawhunt.store.
Appendix: Core Sources
Model and weights: Hugging Face model card · config.json · LICENSE · ModelScope mirror · technical report PDF
Official deployment: vLLM Recipe · vLLM Day-0 blog · SGLang Cookbook · TokenSpeed
Prices verified July 28, 2026: CoreWeave · Lambda · RunPod · GMI Cloud · Vast.ai
API: Alibaba Cloud Model Studio kimi-k3
This article was produced with ten parallel research agents and two adversarial verification tracks. Every critical number—including weight footprint, VRAM verdict, and rental price—was cross-checked against a second source. Figures labeled “estimated” or “unverified” should be treated as provisional until later measurements are available.